Introducing Cerebellum Cloud
Custom models, priced per token.
The simplest way to serve a model. Import weights, get an endpoint, pay for the tokens you use. Nothing billed while idle.
$25 in free credits to start
I · The console
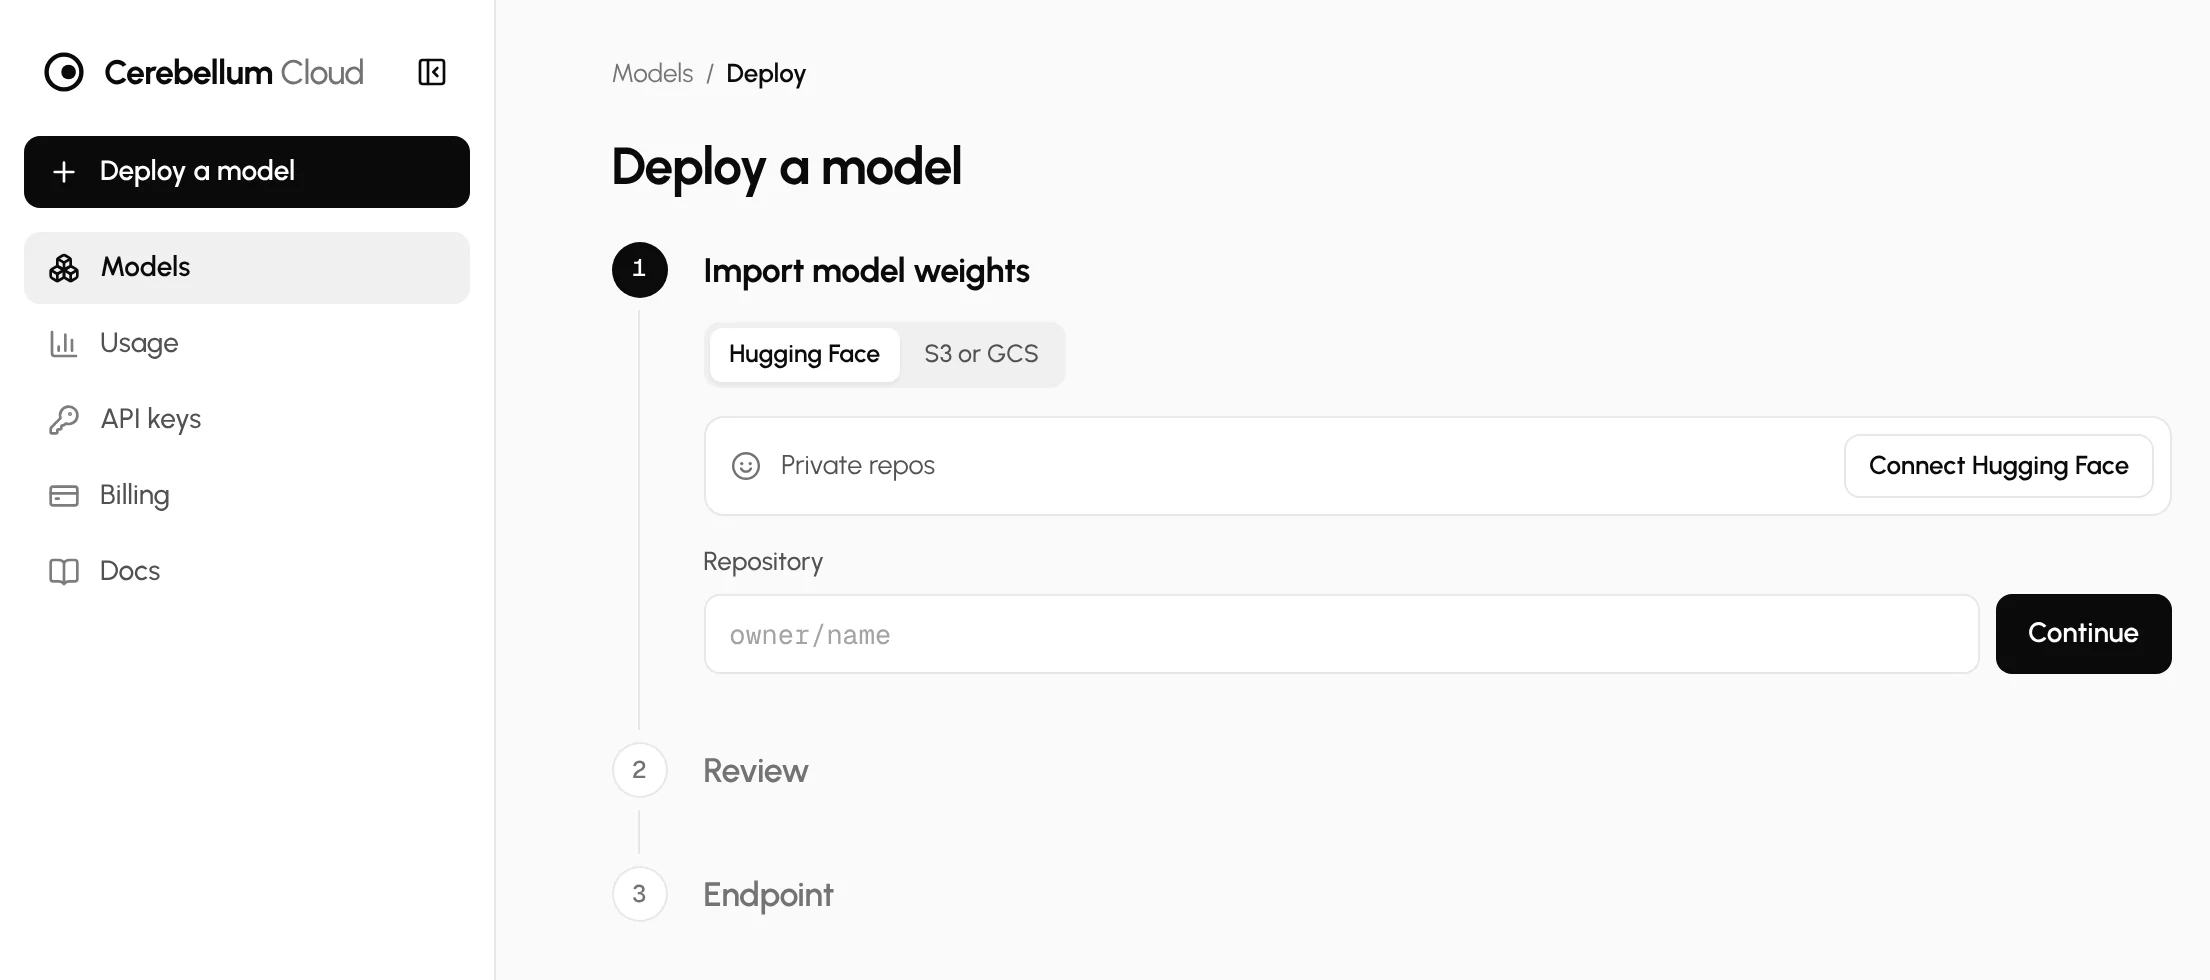
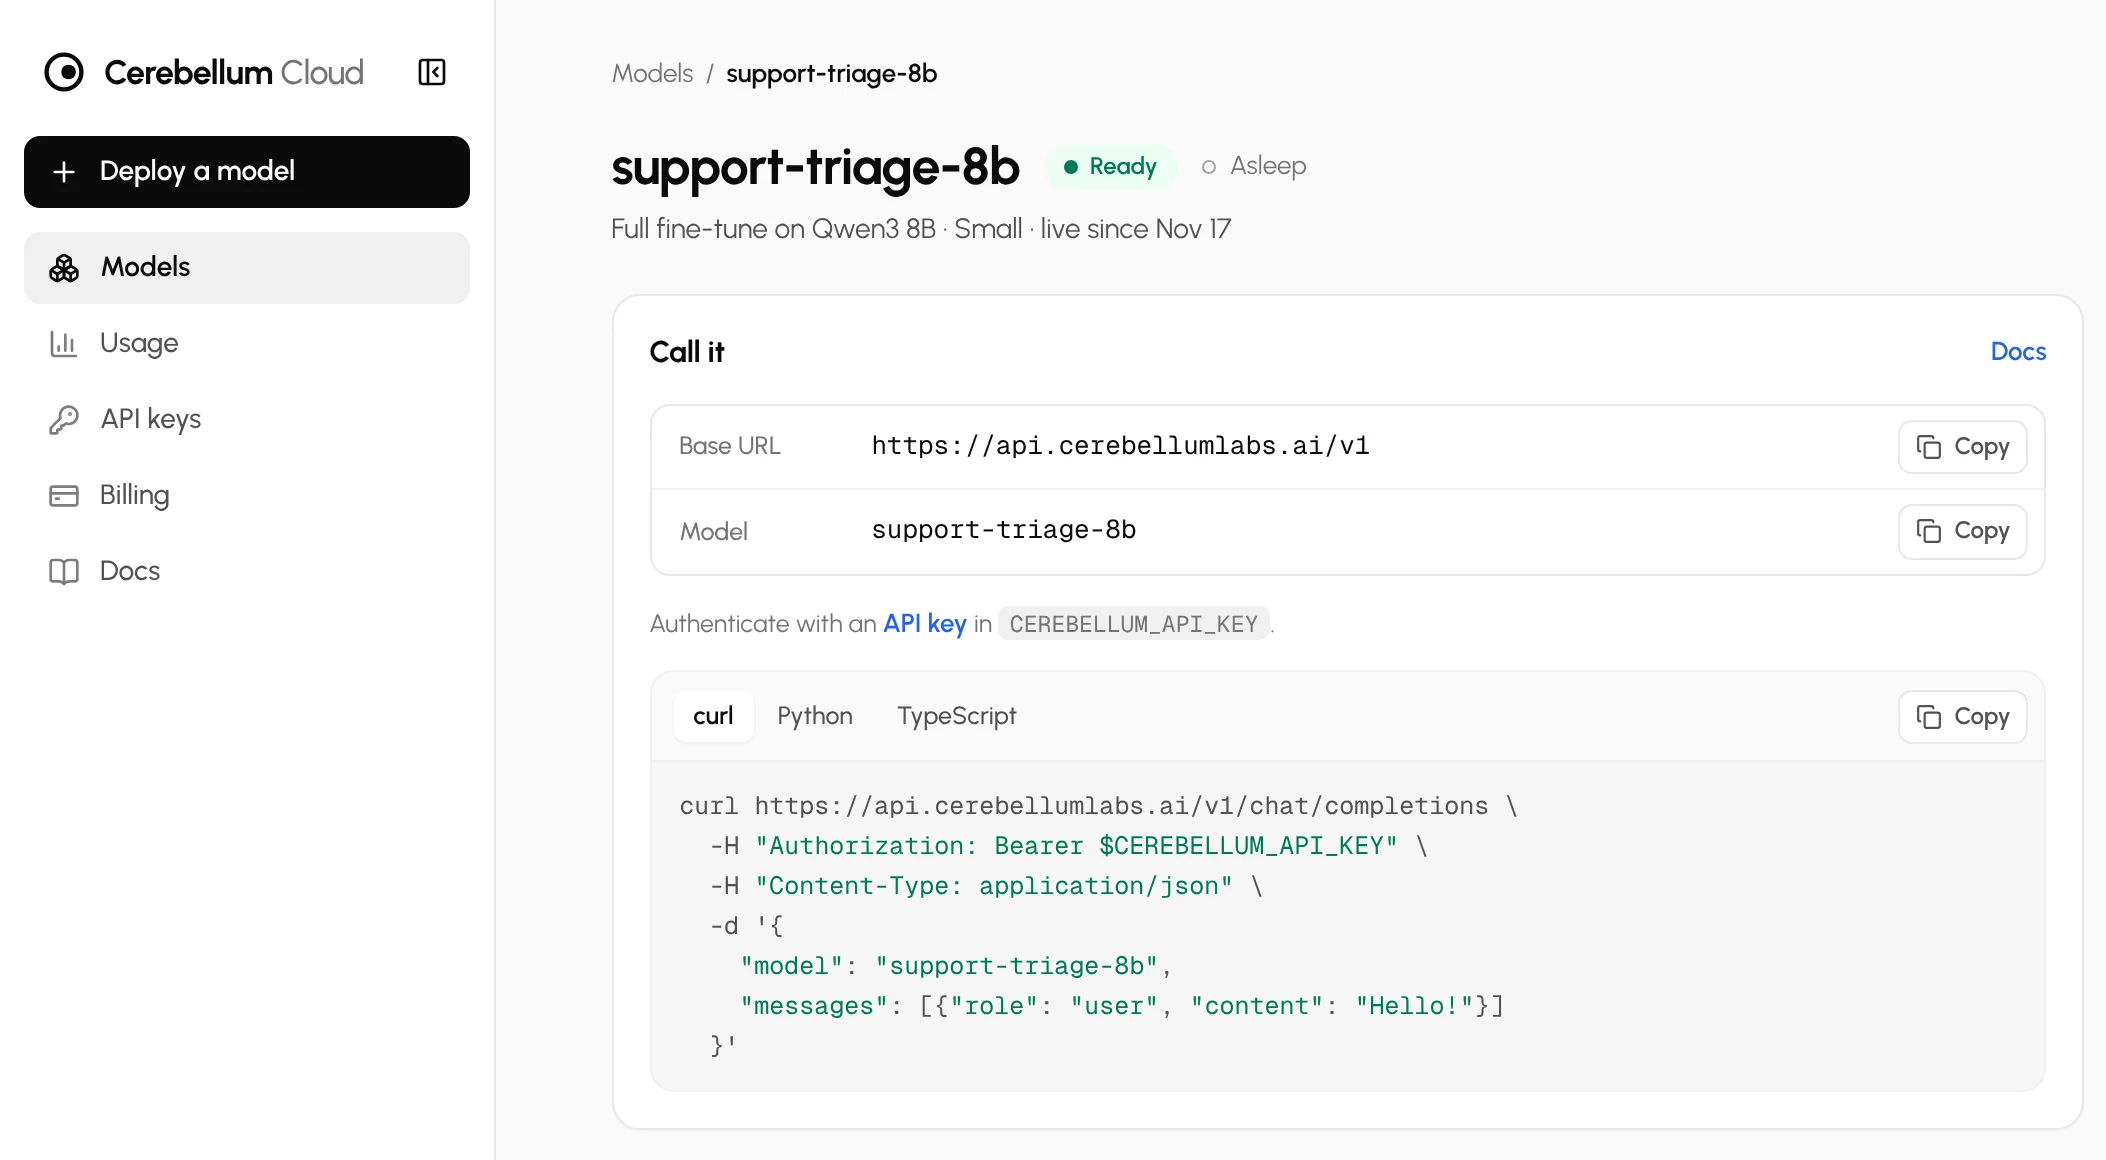
From weights to endpoint.
- 01Import model weightsA Hugging Face repo, private ones included, or S3 and GCS links.
- 02Review and deployBase model, size and price are detected automatically. Confirm to deploy.
- 03EndpointAn API key and an OpenAI-compatible URL.
II · Launch pricing
Priced by size, billed per token.
Pricing is based on the size of the model, which is categorized into three classes: Small, Medium, or Large.
$25 in free credits to start. No expiry.
| Size class | Full fine-tunePer 1M tokens, input / output | LoRA on a listed basePer 1M tokens, input / output |
|---|---|---|
| Smallup to about 14B | $0.75 in / $2.25 out | $0.25 in / $0.75 out |
| Mediumup to about 32B | $1.50 in / $4.50 out | $0.50 in / $1.50 out |
| Large70B in FP8 | $2.50 in / $7.50 out | $1.00 in / $3.00 out |
Listed bases deploy right away
- Qwen3.5 9B
- Qwen3.5 4B
- Qwen3 4B Instruct 2507
- Qwen2.5 7B Instruct
- Qwen3 8B
- Llama 3.1 8B Instruct
- Qwen3.8 27B
- Gemma 4 31B
III · OpenAI-compatible
Change two lines. Keep the code.
Any OpenAI SDK, streaming included.
from openai import OpenAI
import os

client = OpenAI(
    base_url="https://api.cerebellumlabs.ai/v1",
    api_key=os.environ["CEREBELLUM_API_KEY"],
)

resp = client.chat.completions.create(
    model="support-triage-8b",
    messages=[{"role": "user", "content": "Total on this receipt?"}],
)
IV · Questions
FAQ
Which models can be deployed?
Open-weight text models up to 70B in safetensors, from Hugging Face (private repos included) or an S3 or GCS link. Full fine-tunes and merges of any base go live in minutes; LoRA adapters need a listed base. Models with custom code or pre-quantized weights are reviewed first, and nothing is charged until they go live.
What does an idle model cost?
Nothing. Models scale to zero when no requests arrive. The first request after a quiet spell takes longer while the model starts, and it waits rather than failing.
How does billing work?
Per token, from prepaid credits: the input and output tokens of each request, at the model's listed price. No charge for idle time, storage or GPUs. Add credits by card at any time; they never expire. New accounts start with $25 in free credits.
Are prompts or outputs stored?
No. Prompts and outputs are never stored or used for training. Usage records keep only token counts, latency and cost. Weights are used only to serve the model and are deleted when the model is.
Does existing code need to change?
Only the base URL, API key and model name. The API is OpenAI-compatible, so any OpenAI SDK works, with streaming and tool calling.